
Token-Based Approaches to Cloudflare Turnstile at Scale: The API Workflow Explained

Automated test suites, monitoring jobs, and pipelines that collect publicly available data often meet the same constraint: a page may present a challenge before it returns its normal response. Cloudflare Turnstile is one of the most common of those challenges. Instead of asking a person to pick images from a grid, it runs browser and network checks and then issues a short-lived token, which the application’s server verifies before it treats the request as legitimate. That is straightforward at a few URLs, and it becomes an engineering problem across thousands of sessions an hour.
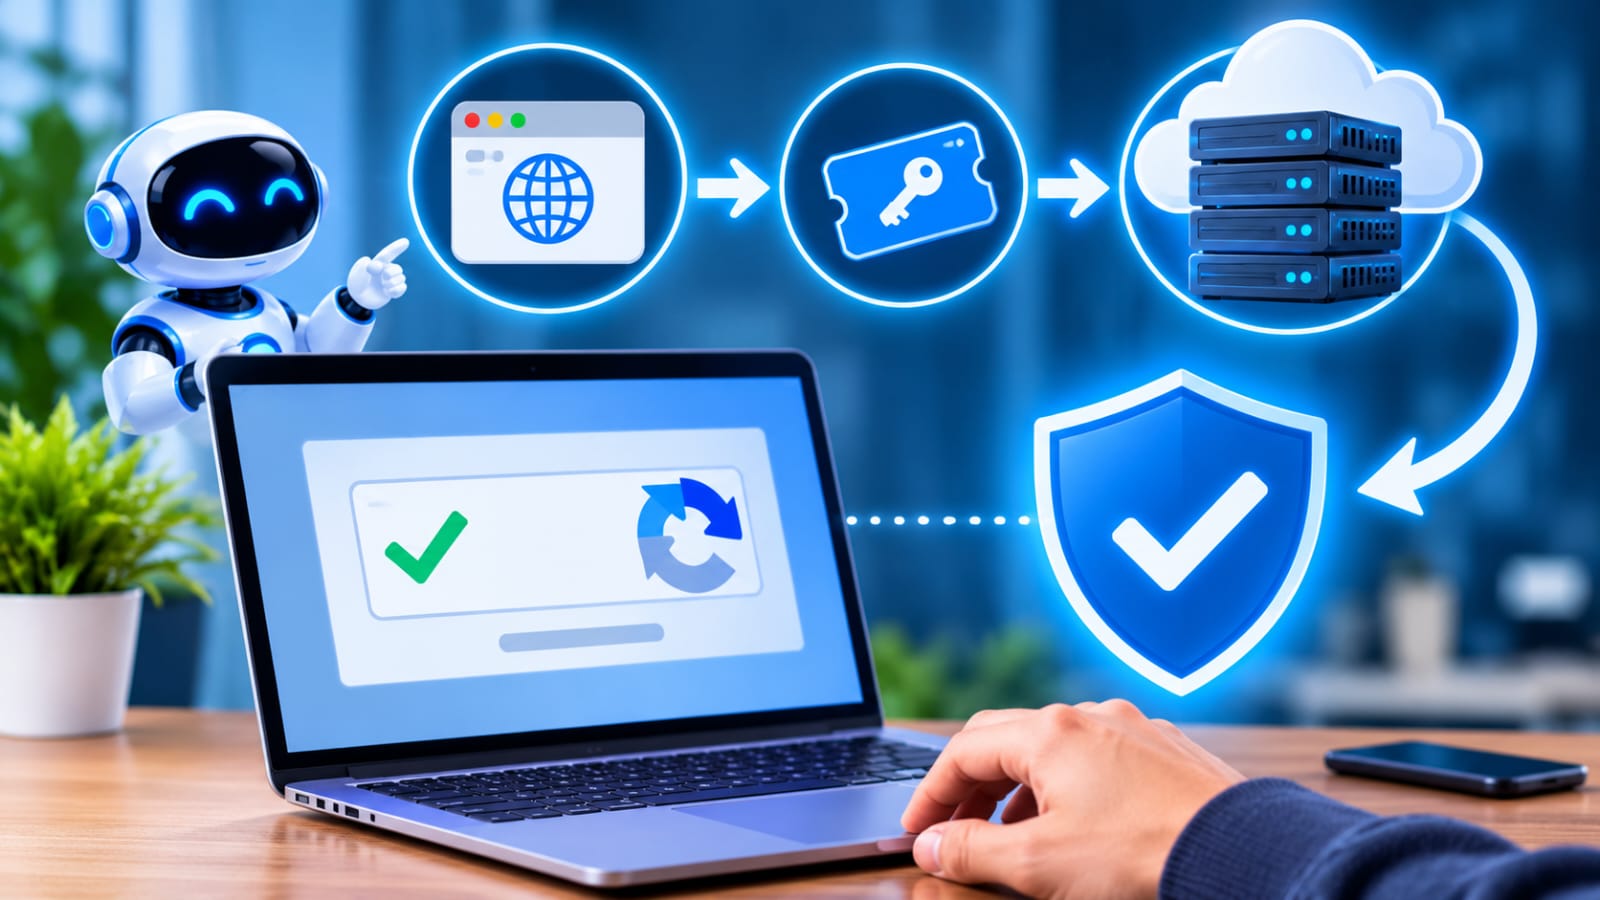
A token-based approach treats the challenge as an API step rather than as a sequence of clicks in a single browser window. The client loads the challenge context, obtains a fresh token, and attaches that token to the request that needs to proceed. For Cloudflare Turnstile, the token is the only artifact the origin needs in order to decide whether the request may continue. Because issuance and verification are separate, a team can scale token production independently of the rest of the HTTP client, and can retry a failed token without restarting an entire workflow.
The workflow is narrow. The client detects that a Turnstile widget, or a managed challenge that results in a Turnstile token, is present, then collects the sitekey and the context the widget expects, typically the page URL, the user agent, and any configured action name. A token-issuing component — an in-house headless browser farm or a token API — returns a response bound to that sitekey. The value is placed in the field the origin checks, commonly cf-turnstile-response, and the request is sent. The application then posts the token to Cloudflare’s siteverify endpoint with the site’s secret, and continues only when verification succeeds. Failed or expired tokens are discarded and replaced, and should never be reused across unrelated sessions.
What does a token-based Turnstile workflow look like in practice?
A token-based Turnstile workflow is a request pipeline that obtains a fresh challenge token through an API or a dedicated worker, attaches that token to the target request, and lets the origin verify it before returning protected content.
At low volume, a single instrumented browser can do every step in one process: open the page, wait for the widget, read the token, and continue. At scale that model breaks down, because browser instances are expensive, challenge latency varies, and jobs stall if each worker has to sit through the check itself. A cleaner design splits the work. A token layer accepts sitekeys and context and returns tokens. An application layer attaches those tokens to the requests it already knows how to make. The two layers can scale, retry, and fail independently.
Some teams use a token API such as CapMonster Cloud to obtain Turnstile tokens from a queue of sitekeys, then inject those tokens into their own HTTP clients. Token issuance is decoupled from the application request, so each layer can be sized for its own workload. Whether tokens come from an in-house browser farm or from a service like CapMonster Cloud, they should be treated as short-lived credentials: requested just before use, passed through once, and dropped if siteverify rejects them.
Operational detail matters as well. Log the sitekey, the page URL, and the verification result, but do not log raw tokens or site secrets. Keep the user agent and other client hints consistent between the token request and the later page request, because mismatches often cause verification to fail. Refresh tokens close to use, and retry the same page when a token is invalid rather than failing the entire run.
When is this workflow the right tool?
This workflow is appropriate when a team has a legitimate need to automate access to pages protected by Turnstile, such as QA testing, permitted collection of publicly available data, or legal web scraping, and must do so at a volume that manual solving cannot support.
In QA, a regression suite may need to reach a form, a search results page, or a public dashboard behind a challenge in staging, following the same path a browser would take, without a person sitting at the widget. In data work, the same pattern appears when a team is allowed to collect content that is already public, and a challenge would otherwise force a human into every request. In both settings the token completes a legitimate request path at volume; it is not a way to reach login-gated or authenticated sessions.
A few design rules keep the workflow within those bounds. Limit it to pages and actions the team is authorized to access. Do not point it at sign-in forms or at sessions that already represent a logged-in user. Prefer documented siteverify behavior, and measure the pipeline by token freshness, verification outcomes, and end-to-end job completion.
Used this way, a token-based approach is an API workflow: detect the challenge, request a short-lived token, attach it, verify it on the origin, and retry when a token expires. That is the shape that holds up when Turnstile appears at scale.




Comment