A polished sample shows what an AI staging tool can produce once. A property team needs to know what it can finish repeatedly.
That requires a small pilot built from the team’s own photographs. The goal is not to collect as many attractive outputs as possible. It is to learn how many source photographs reach an agreed standard, how many attempts they take, how much staff time they consume and what those accepted files cost.
The method below is a reusable test protocol. It is not a completed benchmark, and the images are synthetic examples rather than customer property photographs.
Define one job before choosing the tool
Start with a task your team actually handles. For example: furnish an empty bedroom for a listing illustration while retaining the room’s visible architectural features. Keep furniture removal, lighting adjustments and renovation concepts outside that first test.
Combining several jobs makes the result hard to interpret. If an image looks different after clearing furniture, changing the floor and adding a new style, which step caused the problem? A narrow brief makes it easier to understand both a success and a failure.
Write down the intended use, the person who will approve the file and the requirements of the destination where it will appear. A concept for an internal discussion and an image intended for a public property listing need different review decisions.
Build a small set that reflects your work
Choose photographs you have permission to use and upload. Include an ordinary input, one with a layout challenge and one with less favorable lighting. Add examples that represent recurring jobs in your own portfolio rather than searching only for rooms that make the software look good.
| Input type | Why include it? | Question to record |
| Clear, empty room | Establishes a straightforward starting point | Can the requested furnishing task be completed? |
| Compact room or unusual angle | Tests an input your team may find difficult | Does the arrangement remain plausible for this view? |
| Doorways or fixed features near furniture | Makes constraints explicit | Are those features retained in the result? |
| Darker but usable photograph | Tests a less favorable input | Is the output usable without an unintended change to the room? |
For a first operational trial, four to six different photographs may be manageable. That is a suggested workload, not a statistically representative sample. Record which kinds of properties the set leaves out. If most of your business involves occupied homes, a trial made entirely of empty rooms will not answer your main question.
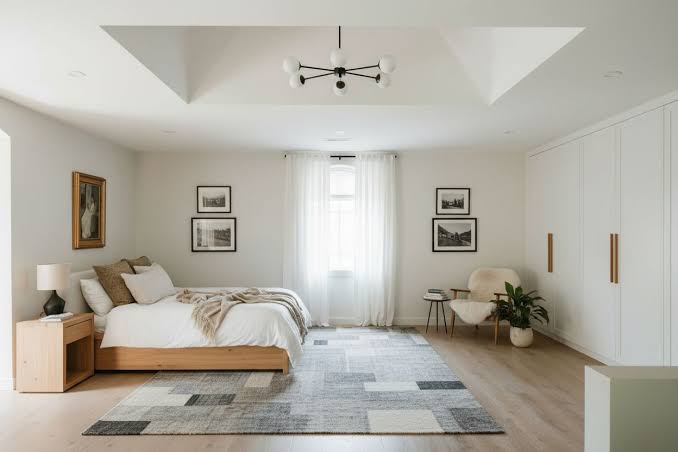
Synthetic bedroom illustration from the Virtual Staging Desk example library. A clear input like this can illustrate the task, but cannot represent every property a team handles.
Keep the brief and the attempt limit consistent
Give each tool the same source files and the same furnishing objective. Use the closest comparable settings where interfaces differ, and record those differences rather than implying every system received identical controls.
Set an attempt limit before starting. For example, a team could allow an initial result and two further attempts per photograph. The precise limit should reflect the team’s available time and budget. Its purpose is to stop an unlimited sequence of retries from being reported as an easy success.
For each run, record the tool, date, selected options, requested change and output file. Save every attempt. A provider update or a different input can change the outcome, so conclusions should remain attached to the conditions under which they were observed.
Track four numbers, not download count
Ten downloaded files do not necessarily mean ten finished jobs. Several may be alternatives for one photograph, while another photograph remains unresolved.
Use one row per source photograph and calculate four operating measures:
| Measure | Calculation | What it reveals |
| Completion rate | Accepted source photographs ÷ source photographs attempted | Whether the tool finishes the assigned job across the test set |
| Median attempts | Middle attempt count among accepted photographs | Whether success usually arrives early or after repeated generation |
| Hands-on minutes | Review, instruction and file-preparation time ÷ accepted photographs | How much staff attention the workflow requires |
| Generation cost | Total generation charges ÷ accepted photographs | The direct tool cost of a usable file, including failed attempts |
Keep uncompleted photographs in the completion-rate denominator. If none is accepted, report that result instead of calculating per-accepted-photo figures with a zero denominator.
An acceptable result should satisfy the original brief and the team’s delivery requirements. Check the actual image rather than assuming a successful download means a successful task. Keep visual preference separate from a material change to the property: disliking a cushion color and losing a doorway are different outcomes.
Furnished synthetic concept from the same library. This is not an output from a pilot conducted for this article, a measured furniture plan or evidence of a tool’s acceptance rate.
Write down why an image failed
“Rejected” is not enough. Separate a matter of taste, such as an unwanted cushion colour, from a change to the property, such as a missing doorway. Record blocked circulation, implausible scale, altered fixed features and rendering artifacts as different failure types.
Keep elapsed time separate from hands-on time. Waiting affects a delivery deadline; reviewing alternatives and rewriting instructions consumes staff attention. State what the cost figure excludes, such as subscriptions, taxes or outside editing.
The same run log can be used to evaluate Virtual Staging Desk or another tool. A gallery explains what an interface can produce; the log shows what happened with your inputs and your acceptance standard.
Test a revision and the final handoff
Choose one result and request a specific change, such as removing a bedside lamp while preserving the remaining arrangement. Record whether the change was possible, what else changed, and how much work was needed to reach a usable version. If a tool does not support that edit, record the limitation instead of quietly substituting a different task.
Then inspect the exported file. Check resolution, format, any watermark and whether the original and final version can be identified reliably. Confirm current usage terms and the destination’s requirements for altered imagery before publication. A trial should cover the output that the team would deliver, not stop at a preview on screen.
A good pilot can end with “keep the existing process.” That is still a useful result if the source files, rejected outputs and run log explain why. Adopt the tool only for the task the pilot actually tested; a successful empty-bedroom trial says nothing about occupied-room cleanup or renovation concepts.