Every enterprise AI post-mortem reads the same way. The model worked fine in testing. The pilot looked good. Then it went into production and started spitting out answers that were wrong, incomplete, outdated or didn’t match up. Leadership points fingers at the model or the vendor. But most of the time, the model wasn’t the issue. The data feeding it was.
Deloitte Digital’s February 2026 study of over 1,000 B2B suppliers and buyers laid this out clearly. Digitally mature organisations that used AI consistently crushed their annual sales growth targets by more than double the margin of their less mature competitors. And the difference didn’t come down to which model they picked. It came down to whether their data foundations could actually hold up under pressure.
Fragmented Systems Create Fragmented Answers
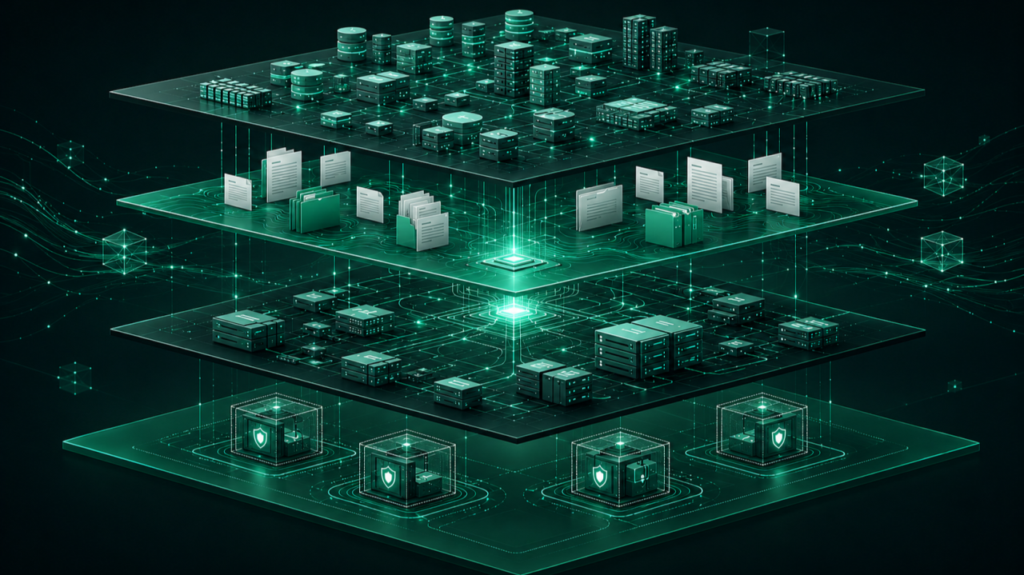
Most enterprises don’t have a single source of truth. They’ve got five or six systems, and each one holds its own version of reality. The CRM says one thing about a customer. The billing platform says something else. The support ticketing system has a completely different set of records. And none of them can even agree on basics like account status, contract terms, pricing tiers or contact details.
When an AI model pulls from these sources, it has no way of knowing which version is right. It just works with whatever it gets. So you end up with outputs that sound confident but contradict each other depending on which system the model happened to query first. That’s not a model problem. It’s a plumbing problem, and you can fine-tune all you want without making a dent in it.
Retrieval Layers That Lag Behind Live Data
Even when the underlying records are clean, the retrieval architecture can cause its own headaches. A lot of enterprise AI setups rely on periodic syncs or cached data stores that fall hours or even days behind the live system.
If you’ve got a chatbot answering questions about order status or inventory levels, that lag turns accurate data into wrong answers. The model is doing exactly what it’s supposed to do. It’s just reasoning over yesterday’s version of things.
Where to Start the Audit
The temptation is to try and fix everything at once, but that’s exactly how data projects drag on for months without delivering a thing. The customer database is usually the messiest place to begin, and it’s also the most consequential because it touches sales, support, marketing and billing all at once.
Publications like CRMs Reviewed examine how different platforms handle data modelling and consistency, which is the layer that determines whether AI reasons over one version of reality or several conflicting ones. Getting the customer record right won’t solve every data problem, but it removes the one that causes the most visible damage.
The Unsexy Part Is the Decisive Part
There’s a reason data cleanup doesn’t get the same attention as model selection or prompt engineering. It’s slow and boring, and you can’t exactly demo a cleaned-up database in a boardroom.
But the Deloitte findings back up something experienced teams already know: the organisations pulling ahead aren’t running better models. They’re running the same models on data that’s actually been organised properly. That’s what makes the difference, and it’s not going to change any time soon.