
MIT SwarmWorld Findings Replicated on Four GPUs Using an Open-Weight AI Model

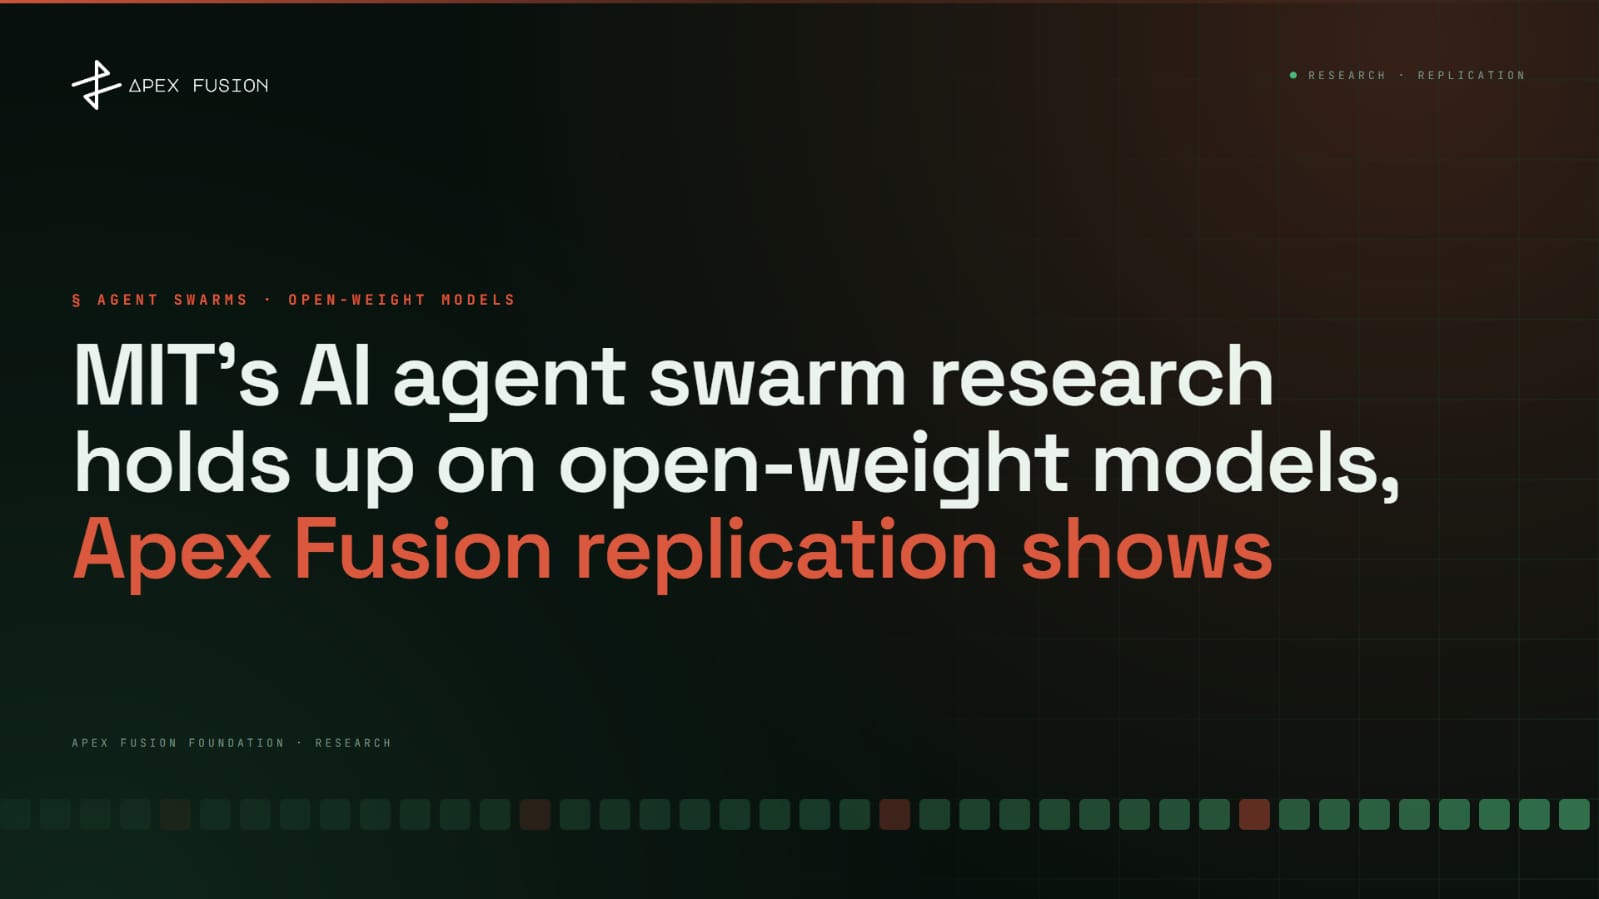
A research team has reproduced most of the central findings of MIT’s SwarmWorld experiment using an open-weight artificial intelligence model running on four consumer graphics cards, suggesting that collective AI-agent behavior may not depend entirely on access to the largest proprietary models.
The replication, conducted by Časlav Nedeljković of HAL8’s AI Local Lab and announced by Apex Fusion Foundation, used a quantized Qwen3.8-27B model to run 50 AI agents inside MIT’s simulated environment. The experiment took approximately 26 hours and involved 12,802 model calls, with the researchers keeping MIT’s code, prompts and commands unchanged.
The findings support the original study’s central conclusion: groups of AI agents can develop more resilient collections of technologies than individual agents working independently. However, the replication also identified differences in model-serving configurations and a reproducibility issue in MIT’s released simulation traces, leaving questions for further testing. <FileCite ref_id=”turn5file1″ />
What is MIT’s SwarmWorld experiment?
SwarmWorld is a simulated environment developed by researchers at MIT’s Laboratory for Atomistic and Molecular Mechanics to study how AI agents discover, develop and share technology when they interact over time.
Rather than assigning agents predefined jobs or providing recipes for completing tasks, the experiment gives them access to resources, materials and tools. Agents can conduct experiments, construct persistent artifacts and develop programs that continue operating after the agents themselves are removed.
The original research found that societies of agents could build broader and more resilient technology portfolios than the strongest individual agent selected from an equally sized group. Agents could also develop informal divisions of labor, with some focusing on exploration and others on construction.
The replication tested whether these results would persist when the underlying model and computing setup changed.
What did the open-weight replication find?
The team used Qwen3.8-27B in a 4-bit GPTQ configuration, served through vLLM on four NVIDIA RTX 3090 graphics cards. It ran the experiment across four world seeds and four experimental conditions.
Nine of the 12 paired effects measured in the replication matched the direction of MIT’s original results. Portfolio resilience—the central collective advantage identified in the original research—remained positive across all tested culture conditions and was stronger in the replication.
The experiment also reproduced a pattern of spatial self-organization. In societies with shared culture, agents clustered around their artifacts, while groups without explicit culture or communication showed less concentrated behavior.
One result stood out: the smaller model performed less effectively when operating alone but benefited more from working within a society.
The replication’s Qwen3.8-27B model reached six of 16 research milestones in the solo condition, compared with seven to 10 for MIT’s original model. Within a full-culture society, however, the replicated model reached all 16 milestones, while MIT’s model reached 14.
This suggests that collaboration can compensate for some limitations in individual model performance. It does not establish that smaller models will outperform larger models across all agent tasks; the result applies to the tested environment and experimental conditions. <FileCite ref_id=”turn5file1″ />
Why model configuration may matter as much as model size
The replication uncovered a technical variable that could affect how AI research results are reproduced: the precision used for a model’s key-value (KV) cache, which stores information used during generation.
Two 4-bit builds of the same 27-billion-parameter model produced different scores in MIT’s validity pilot. The GPTQ build scored 0.41, compared with 0.24 for another configuration. The difference exceeded the gap between the tested 27-billion-parameter model and a 235-billion-parameter model in the reported comparison.
The researchers suspect that KV-cache precision contributed to the discrepancy, but they have not completed a control experiment to establish the cause.
The finding highlights a practical challenge for AI research. Publishing model weights and experiment code may not be sufficient to reproduce results if serving configurations, numerical precision and runtime settings also influence outcomes.
The team also reported a separate issue with MIT’s public simulation traces. Although the released traces reproduced observable events and metrics, six of seven tested traces failed a hidden-state check at points within the simulation. The researchers submitted a GitHub issue and a pull request to the original project.
These findings do not invalidate the original SwarmWorld results. They identify implementation details that require clarification and further testing. <FileCite ref_id=”turn5file1″ />
What does Apex Fusion’s Vector network add?
The replication also provided a limited test of Vector, Apex Fusion’s settlement infrastructure for AI agents. The network is designed to record agent activity, meter model usage and create auditable onchain receipts for work performed.
In the test, the researchers registered their model server as a supplier on Vector’s OpenAI-compatible inference marketplace. The proposed model allows requests to be metered and settled through the network, creating a record of activity that can be inspected afterward.
However, the scale of the test matters. Only a 32-call pilot ran through Vector’s gateway; the main experiment of approximately 12,800 calls ran directly through the researchers’ infrastructure. The pilot produced 329 executed actions, compared with 320 on the direct path, with identical research scores.
A full comparison remains pending, so the results do not yet demonstrate that Vector can handle the entire experiment at scale or that onchain settlement has no effect on performance.
The distinction is important because AI-agent infrastructure has two separate requirements: generating useful outputs and accounting for the work behind them. A settlement layer can potentially provide evidence of which service handled a request, how usage was measured and what was charged, but those records do not independently establish that an agent’s output is accurate or useful.
Apex Fusion says Vector is intended to provide agent identity, bonded settlement, dispute resolution and verifiable receipts. The replication offers an early demonstration of its inference gateway, rather than a full production-scale validation of those capabilities. <FileCite ref_id=”turn5file1″ />
What happens next for multi-agent AI research?
The replication adds evidence that collective AI-agent behavior can persist when researchers switch from a hosted frontier model to a smaller open-weight model running on locally controlled hardware.
Its limitations remain significant: the experiment was conducted by one research team, used four world seeds and a single sample per episode, and left both the KV-cache hypothesis and the complete Vector integration comparison unresolved.
The next tests include isolating the effects of KV-cache precision, running MIT’s original model on the same infrastructure, expanding the Vector marketplace comparison and testing a population of 100 agents.
For developers, the broader lesson is that building multi-agent systems requires more than choosing a capable language model. Model configuration, reproducible simulation environments and reliable records of agent activity may all influence whether results can be repeated and deployed.
The SwarmWorld replication supports the case for further research into AI societies on accessible hardware. Whether the same collective advantages hold across different models, larger populations and real-world tasks remains an open question.




Comment