Most explanations of AI photo animation fall into two camps. One is marketing copy that calls it “magic.” The other is a research paper full of equations that most people will never read.
I wanted something in between. So over a few weeks, I ran the same set of photos through an image-to-video workflow again and again, changing one variable at a time, and paid attention to why certain clips worked and others fell apart. This is what I learned about what’s happening under the hood, and how that knowledge translates into better results.
The Short Version of the Technology
Image-to-video models are, in most current systems, built on the same diffusion approach that powers AI image generators. The difference is that instead of producing one frame, the model produces a sequence of frames that have to agree with each other.
In plain terms, the process looks roughly like this:
- The model reads your photo. It builds an internal representation of what’s in the image: a face, a background, lighting direction, depth.
- It predicts plausible motion. Based on patterns learned from huge amounts of video, it estimates how this kind of scene usually moves. Faces blink. Water ripples. Cameras drift.
- It generates frames in sequence, using your original photo as an anchor so the subject stays recognizable.
- It enforces consistency between frames so the clip doesn’t flicker or morph.
Step four is where most of the difficulty lives, and where most of the visible failures come from.
Why Faces Are the Hardest Test
Humans are extremely sensitive to faces. We’ll forgive a cloud moving strangely, but if someone’s eye shape changes for a single frame, it reads as wrong immediately.
That’s why identity preservation is the first thing I check in any tool. In my tests, the clips that failed almost always failed the same way: the face slowly drifted away from the original over the length of the clip. By the last frame, the person looked like a cousin of themselves.
Two things consistently reduced that drift:
- Shorter clips. The further a model gets from the anchor frame, the more room it has to wander.
- Less requested motion. A blink and a slight smile keep the face close to the source. A full head turn forces the model to invent a side of the face it has never seen.
My Test Setup
To keep things fair, I used three categories of source images:
- A product photo: a glass bottle on a wooden surface, shot in daylight
- A modern portrait: a well-lit headshot from a phone camera
- An old photograph: a scanned black-and-white family portrait, roughly seventy years old, with visible grain and a crease
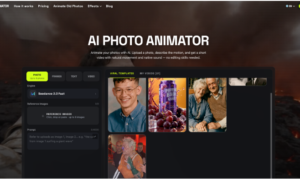
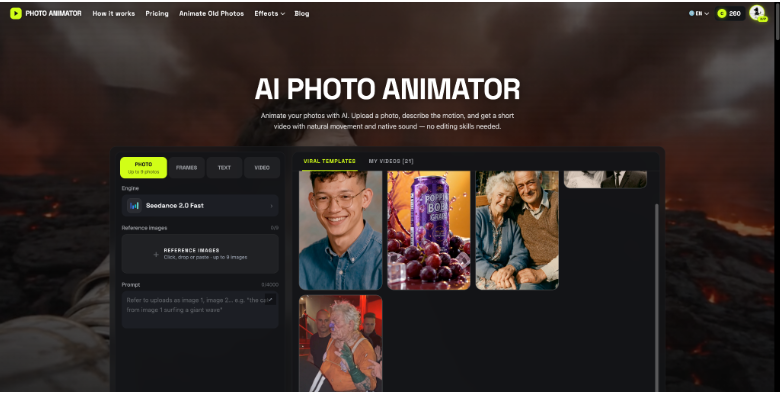
Most of the testing ran through AI Photo Animator, mainly because it works in the browser and lets me rerun the same image with different motion templates quickly, which is what this kind of side-by-side testing needs. For each image I generated several clips per motion type and compared them frame by frame.
Test 1: The Product Photo
This was the easiest category. A slow camera push-in looked clean almost every time. Light reflections on the glass shifted in a believable way, which honestly surprised me.
Where it broke: when I asked for the bottle itself to rotate. The model had no idea what the back of the label looked like, so it invented one, and the text turned into nonsense. That’s a general rule I’d now apply to any tool: the model can move the camera far more reliably than it can move the object, because camera motion mostly reuses pixels it already has.
Test 2: The Modern Portrait
Subtle expressions worked well. A blink, a small smile, a slight tilt: these looked natural in most generations.
Larger motions were inconsistent. Turning the head more than a few degrees revealed the “invented side” problem again: ears changed shape, hairlines shifted. Hands entering the frame were the worst. If a hand wasn’t visible in the original, I stopped asking for one.
Test 3: The Old Photograph
I expected this to be the weakest category. Old photos are low resolution, grainy, and often damaged, which seemed like the worst possible input.
It turned out to be where preparation mattered most. My first attempt, using a quick phone snapshot of the print, produced a smeared, waxy face. The second attempt went very differently:
- I rescanned the print at 600 DPI on a flatbed scanner
- I repaired the crease before doing anything else
- I used a workflow designed to bring old family photos to life rather than a general-purpose setting, since it handled film grain and low contrast more gracefully
- I limited the motion to a blink and a faint smile
The result was the most convincing clip of the entire test. My guess is that the minimal motion and the strong anchor image gave the model very little room to drift. And unlike the product shot, the emotional payoff was immediate. Family members who saw it didn’t comment on the technology at all.
What the Failures Taught Me
Looking back across all the clips, the bad results traced back to a small set of causes:
- Asking the model to invent unseen information (the back of an object, the side of a face, a hand outside the frame)
- Too much motion for the clip length
- Weak source images, where the model had to guess at missing detail
- Text inside the frame, which current models still struggle to keep legible
Each of these is really the same problem: the further the output has to move away from the pixels in the original photo, the more the model is guessing.
A Practical Checklist Based on How the Models Work
If you understand the mechanics, the best practices almost write themselves:
- Start from the best possible source. High resolution, good light, sharp focus.
- Crop to your final aspect ratio first, so the model isn’t inventing edges later.
- Prefer camera motion over object motion when you need reliability.
- Request one motion per clip, and keep it modest.
- Generate several versions; variation between runs is normal.
- Check the first and last frames against the original. If the face drifted, discard it.
Where This Technology Is Heading
The weak spots I ran into, like identity drift, invented geometry, and garbled text, are exactly the problems the field is actively working on. Each model generation I’ve tried holds faces more steadily than the last.
For now, the most useful mindset is to treat image-to-video AI as a collaborator with a short memory: give it a strong anchor, ask for something simple, and it will often surprise you. Ask it to imagine too much, and you’ll see the seams.