
Artificial intelligence is moving rapidly from experimentation into core enterprise operations. Financial institutions, insurers, healthcare organizations, retailers, and other large companies are investing in generative AI, machine learning, predictive analytics, intelligent automation, and increasingly autonomous systems.
But moving AI from a proof of concept into a production environment remains far more difficult than simply selecting a model.
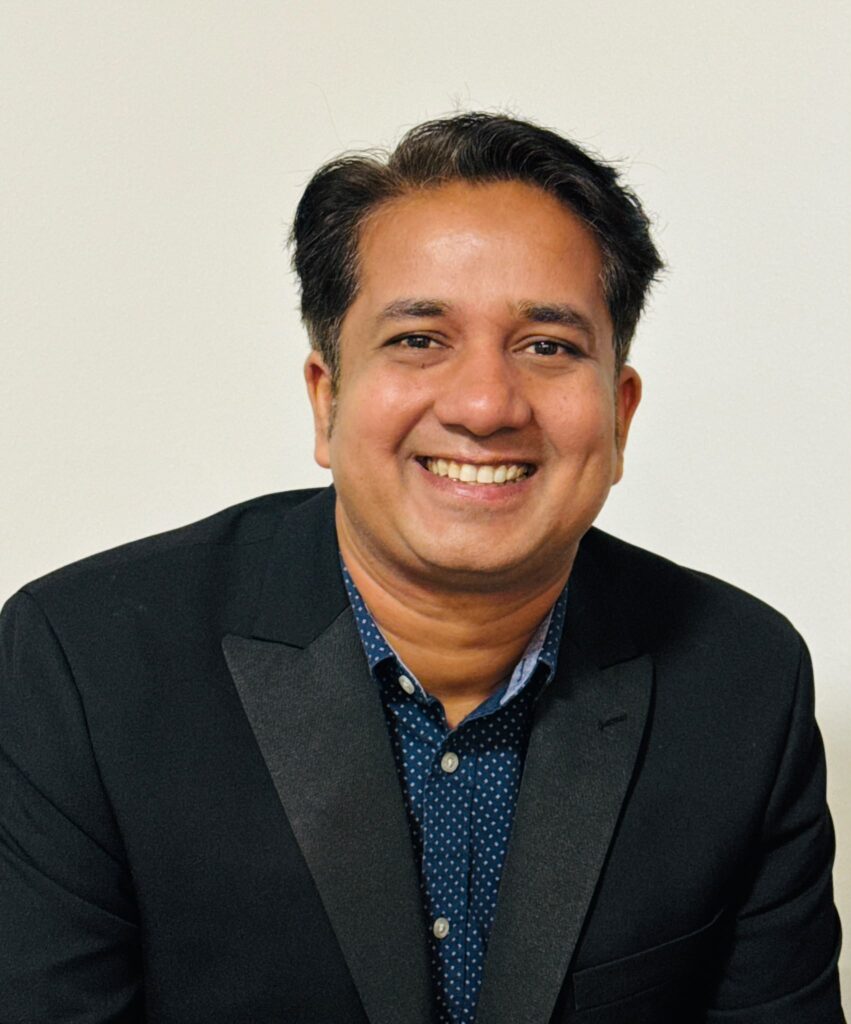
For Vikrant Sikarwar, a Principal Data Engineer specializing in enterprise data engineering, cloud architecture, artificial intelligence, and large-scale modernization, the central challenge is architectural.
“The biggest mistake organizations can make is to think of AI as an isolated layer that can simply be added on top of fragmented data systems,” Sikarwar says. “Enterprise AI has to be supported by a broader architecture where data ingestion, processing, domain context, governance, security, quality, observability, and intelligent services work together.”
That perspective reflects a wider shift taking place across enterprise technology. The traditional data platform is evolving into something broader: an intelligent enterprise architecture capable of supporting analytics, real-time processing, machine learning, generative AI, and eventually autonomous agents.
Moving Beyond the Traditional Data Platform
Enterprise data platforms were historically designed around reporting, analytics, and data warehousing. Over time, they expanded to include cloud storage, distributed processing, streaming, data lakes, lakehouses, governance platforms, and machine learning environments.
AI is now forcing another architectural transition.
Modern enterprises often operate hundreds or thousands of systems containing overlapping and sometimes inconsistent information. Critical data may exist across operational databases, SaaS applications, APIs, event streams, files, cloud platforms, and legacy systems. The resulting challenge is not that these technologies inherently lose data, but that information can become fragmented, duplicated, stale, or interpreted differently across systems.
The challenge is therefore no longer simply moving data from one location to another. It is creating an architecture capable of understanding, governing, and operationalizing that information across multiple consumption patterns.
Sikarwar views the modern enterprise data platform as a set of interconnected capabilities rather than a single technology stack.
“The value comes from how these capabilities work together,” he says. “A lakehouse alone is not an AI strategy. A streaming platform alone is not an AI strategy. A governance catalog alone is not an AI strategy. The architecture has to connect all of them.”
A Unified Data Integration Foundation
The first requirement of an AI-ready architecture is the ability to integrate information from diverse enterprise systems.
Organizations increasingly need to support batch processing, files, APIs, change data capture, event streams, operational databases, and SaaS platforms at the same time. Each pattern serves a different purpose.
Batch processing remains appropriate where latency is not critical. Change data capture can efficiently move transactional changes. Event-driven patterns are useful when business decisions need to respond quickly.
Sikarwar argues that mature architecture should support the business requirement rather than force every workload into one technology pattern.
A unified integration foundation also benefits from standardized engineering practices. Instead of building every data flow independently, enterprises can create common approaches for connectivity, validation, retry logic, error handling, observability, schema management, security, and recovery.
This reduces repetitive engineering effort and creates more predictable operational behavior across the platform.
Standardizing Data Processing at Scale
Once data enters the environment, it must be transformed, enriched, reconciled, and prepared for downstream consumption.
For large organizations, that processing layer needs to handle both scale and continuous change. Cloud platforms and distributed processing frameworks make it possible to process massive datasets efficiently, but production systems need more than raw performance. They also need resilience.
Sikarwar has worked extensively with enterprise modernization initiatives involving cloud data platforms, distributed processing, analytics, and large-scale reporting transformation.
His experience includes modernization programs involving the migration of more than 100 enterprise reporting assets and the retirement of multi-terabyte legacy environments.
He sees standardization as one of the most important factors in scaling enterprise engineering.
“Engineering teams should not have to solve the same operational problems repeatedly,” Sikarwar says. “If retry behavior, logging, quality controls, lineage, or recovery can be standardized, those capabilities should become part of the platform itself.”
Domain Context: The Missing Layer in Many AI Systems
One of the biggest challenges facing enterprise AI is not access to raw data but business meaning.
A system may contain millions of records and still lack the context required to interpret them correctly. Terms such as customer, account, policy, claim, transaction, product, eligibility, or risk can have different definitions across systems and business units.
This is why Sikarwar sees domain-oriented architecture as a critical part of AI readiness. Domain models establish shared business entities, relationships, definitions, and rules across an enterprise. They help bridge the gap between technical structures and business meaning.
This becomes increasingly important as AI systems are asked to reason across multiple datasets. A generative AI model may understand the general meaning of a claim or transaction, but it does not automatically understand how a specific organization defines claim status, customer eligibility, risk exposure, or operational workflow.
“AI needs context, not just access,” Sikarwar says. “If the architecture does not provide business meaning, the model may be technically capable but operationally unreliable.”
He has also explored AI-augmented approaches to enterprise domain modeling, examining how artificial intelligence can assist architects and engineers in analyzing schemas, documentation, relationships, and usage patterns. But he emphasizes that AI should assist domain modeling rather than replace human validation.
“The strongest approach combines machine intelligence with business expertise,” he says.
Data Quality and Observability as Architectural Capabilities
Data quality has often been treated as a downstream control. In AI-enabled environments, Sikarwar argues that it needs to become part of the architecture itself.
Production AI systems can consume information from many different sources and act on that information quickly. That increases the impact of stale, incomplete, inconsistent, duplicated, or incorrect data.
A modern data-quality framework therefore needs to monitor more than traditional rule violations. It also needs to understand freshness, schema changes, distribution shifts, reconciliation issues, unexpected anomalies, and the overall health of the data flowing through the platform.
Observability adds another layer by helping engineering teams understand not just whether a pipeline failed, but whether the underlying data itself changed in a way that could affect downstream systems.
Sikarwar has also researched AI-driven approaches to data quality. Machine learning can complement deterministic business rules by detecting patterns or anomalies that fixed controls may not anticipate.
This creates a two-way relationship between AI and data quality: enterprises need reliable data to build dependable AI, while AI itself can help organizations monitor and improve data quality.
Governance, Lineage, Privacy, and Security
As enterprise AI becomes more capable, governance becomes increasingly important.
Organizations need to know where data originated, how it was transformed, who owns it, what systems consumed it, whether it contains sensitive information, and whether a user or AI system is authorized to access it.
This requires an architecture where governance is built into the platform rather than treated as a separate compliance activity.
Lineage is particularly important. If an AI system produces a recommendation based on information from several datasets, enterprises increasingly need the ability to trace those inputs back through transformations and source systems.
Security must also become more granular. Traditional access-control models were designed primarily for human users and predefined applications. AI agents create a different challenge because they may operate across multiple systems, dynamically retrieve information, and potentially initiate actions.
Sikarwar believes future enterprise architectures will need stronger identity, policy, authorization, and traceability controls for non-human actors.
“An AI agent should not receive unrestricted access simply because it is useful,” he says. “Identity, permissions, purpose, and accountability need to be designed into the architecture.”
Metadata as a Supporting Control Layer
Metadata remains important, but in Sikarwar’s view it should function as part of a broader architectural framework rather than as a standalone strategy.
Metadata can describe technical structures, ownership, data sensitivity, business definitions, lineage, processing rules, quality expectations, and access policies.
Used effectively, it can help connect engineering, governance, security, and domain context. Its value comes from enabling the architecture to behave more consistently.
“Metadata becomes powerful when it drives behavior,” Sikarwar says. “It should help the platform understand how data is processed, governed, secured, and consumed.”
In that sense, metadata acts as a supporting control layer rather than the center of the architecture.
Real-Time and Event-Driven Architecture
AI adoption is also increasing demand for timely information. Many enterprise workloads can still operate efficiently through scheduled batch processing. Others cannot.
Fraud detection, operational risk, customer interaction, claims processing, financial monitoring, recommendation systems, and automated decisioning may require information within seconds or minutes.
This is where event-driven architecture becomes strategically important. Technologies such as event streams, message brokers, change data capture, and streaming analytics allow systems to respond as business events occur.
Sikarwar has researched the architectural tradeoffs between real-time and batch processing. He argues that real time should be used where business value justifies the additional complexity.
Streaming systems require careful design around event ordering, state management, replay, fault tolerance, duplicate handling, observability, scalability, and recovery.
“Real-time architecture should solve a real-time business problem,” he says. “It should not be adopted simply because it is technically interesting.”
The Intelligent Services Layer
Once an enterprise establishes a trusted data foundation, it can begin to build intelligent services on top of it.
These services may include machine learning, predictive analytics, generative AI, retrieval-augmented generation, recommendation engines, intelligent automation, AI assistants, and increasingly autonomous agents.
Sikarwar believes these capabilities should consume enterprise data through governed and controlled interfaces rather than connect directly to fragmented source systems.
That architectural separation improves consistency, security, portability, and control. It can also make the enterprise less dependent on a single model or AI vendor.
“The architecture should make AI replaceable,” Sikarwar says. “Organizations should avoid designing the entire data ecosystem around one model or one provider.”
The data and governance foundation should remain stable even as models, tools, and vendors continue to change.
From MLOps to Enterprise AI Operations
Building an AI model is only the beginning. Production AI requires operational discipline.
That includes deployment, monitoring, versioning, rollback, performance tracking, security, governance, cost management, and auditability.
Generative AI adds additional concerns such as prompt management, retrieval quality, hallucination monitoring, access control, response validation, model selection, latency, and usage cost.
AI agents create an even broader operational challenge because they may interact with systems and initiate actions.
Sikarwar sees this as an evolution of traditional MLOps into a broader enterprise AI operating model.
Organizations will increasingly need to manage not only models, but also prompts, policies, data context, identities, permissions, and execution history.
“The production problem is much larger than model deployment,” he says. “Organizations need operational controls around the full AI system.”
From Project-Based Engineering to Platform Engineering
The architecture ultimately exists to support business outcomes.
Different users and systems need different ways to consume data and intelligence. Business teams may use dashboards and reporting applications. Data scientists may require curated datasets. Applications may consume APIs. AI assistants may retrieve governed knowledge. Operational systems may react to events. Autonomous agents may eventually coordinate workflows across multiple platforms.
A strong architecture should support these patterns without creating a separate data silo for every new use case.
Sikarwar describes this as a shift from project-oriented engineering to platform-oriented engineering.
Instead of repeatedly building isolated solutions, enterprises create reusable capabilities that can support many business teams and technical workloads. This approach becomes particularly important as AI use cases multiply across an organization.
Moving AI from Proof of Concept to Production
The challenges of operationalizing AI were also a major topic at FinovateSpring 2026 in San Jose, where Sikarwar participated in a panel focused on moving artificial intelligence from proof of concept to production.
A proof of concept can succeed under controlled conditions. Production is different.
Enterprise systems must integrate with real data, existing applications, security controls, regulatory requirements, changing schemas, operational processes, and production support models.
That is why technically successful demonstrations can still fail to scale.
“The model is only one component,” Sikarwar says. “Production AI requires a complete architecture around it.”
That architecture includes data engineering, platform engineering, domain context, security, governance, observability, real-time processing, and clear operational ownership.
Research, Publications, and Professional Contribution
Alongside his enterprise engineering work, Vikrant Sikarwar has authored and published research spanning artificial intelligence, data engineering, enterprise architecture, cloud modernization, data quality, domain modeling, and real-time processing.
His research examines how emerging AI capabilities can be applied to practical challenges in large-scale enterprise data environments, including scalable engineering, intelligent data-quality management, domain understanding, modernization, and real-time decision support.
His published research includes work on intelligent data engineering, AI-driven data quality, AI-augmented enterprise domain modeling, and architectural considerations for real-time versus batch processing, reflecting a broader focus on building enterprise platforms capable of supporting both traditional analytics and emerging AI workloads.
Rather than treating these as isolated research topics, Sikarwar views them as connected parts of the same enterprise problem: how to create data platforms that are reliable enough for day-to-day operations while also being flexible and intelligent enough to support emerging AI workloads.
His research perspective is closely connected to his industry experience. The architectural questions explored in his publications—how to improve data quality, how to standardize engineering, how to introduce intelligence into domain modeling, and how to determine when real-time processing creates business value—are the same types of challenges enterprises encounter when modernizing complex data environments.
Sikarwar also contributes to the broader engineering and research community through peer review. He has served as a reviewer for IEEE publications and international technology conferences, evaluating submitted research for technical soundness, methodology, novelty, experimental quality, and contribution to the field.
Sikarwar is an IEEE Senior Member and Fellow of IETE. He also participates in industry discussions, technical presentations, and professional activities related to artificial intelligence, enterprise data architecture, and data engineering.
The Evolution of the Data Engineer
The architectural shift is also changing the role of the data engineer.
Traditional data engineering focused heavily on ETL, data warehousing, and reporting. Modern data engineers increasingly work across cloud platforms, distributed processing, streaming, domain modeling, APIs, governance, data quality, observability, security, machine learning platforms, generative AI, and intelligent automation.
The profession is becoming more architectural.
Sikarwar believes future data engineers will need to understand not only how information moves, but how enterprise systems interpret, govern, secure, and operationalize it.
“The role is moving from pipeline builder to platform architect,” he says. “The engineer increasingly has to understand the entire lifecycle of enterprise information.”
Toward an AI-Ready Enterprise Architecture
AI models will continue to change. The architecture underneath them will need to endure.
For Sikarwar, the strongest enterprise AI strategy is therefore not centered on a single model, tool, or platform. It is centered on building an architecture capable of supporting different forms of intelligence safely and reliably.
That means creating an environment where enterprise integration, scalable processing, domain context, quality, observability, governance, security, real-time systems, intelligent services, and operational controls reinforce one another.
Metadata can help connect these capabilities, but it is one part of the broader system rather than the central idea.
“Enterprise AI should not be built as a layer sitting on top of fragmented systems,” Sikarwar says. “It should be part of an architecture where data, governance, security, domain context, real-time processing, and intelligent services operate together.”
Ultimately, the next phase of enterprise AI will not be defined by who adopts the newest model first, but by who builds the strongest foundation to use intelligence at scale.
Organizations that bring together data, architecture, governance, security, business context, and operational discipline will be better positioned to turn AI from experimentation into lasting business value.
As Sikarwar sees it, the real opportunity is not simply to build smarter models, but to design enterprise systems capable of becoming smarter, more adaptive, and more trusted over time.






































