
From Large-Scale AI Agents to Reliable AI: Researcher Rui Yang Explores the Future of Autonomous Intelligent Systems

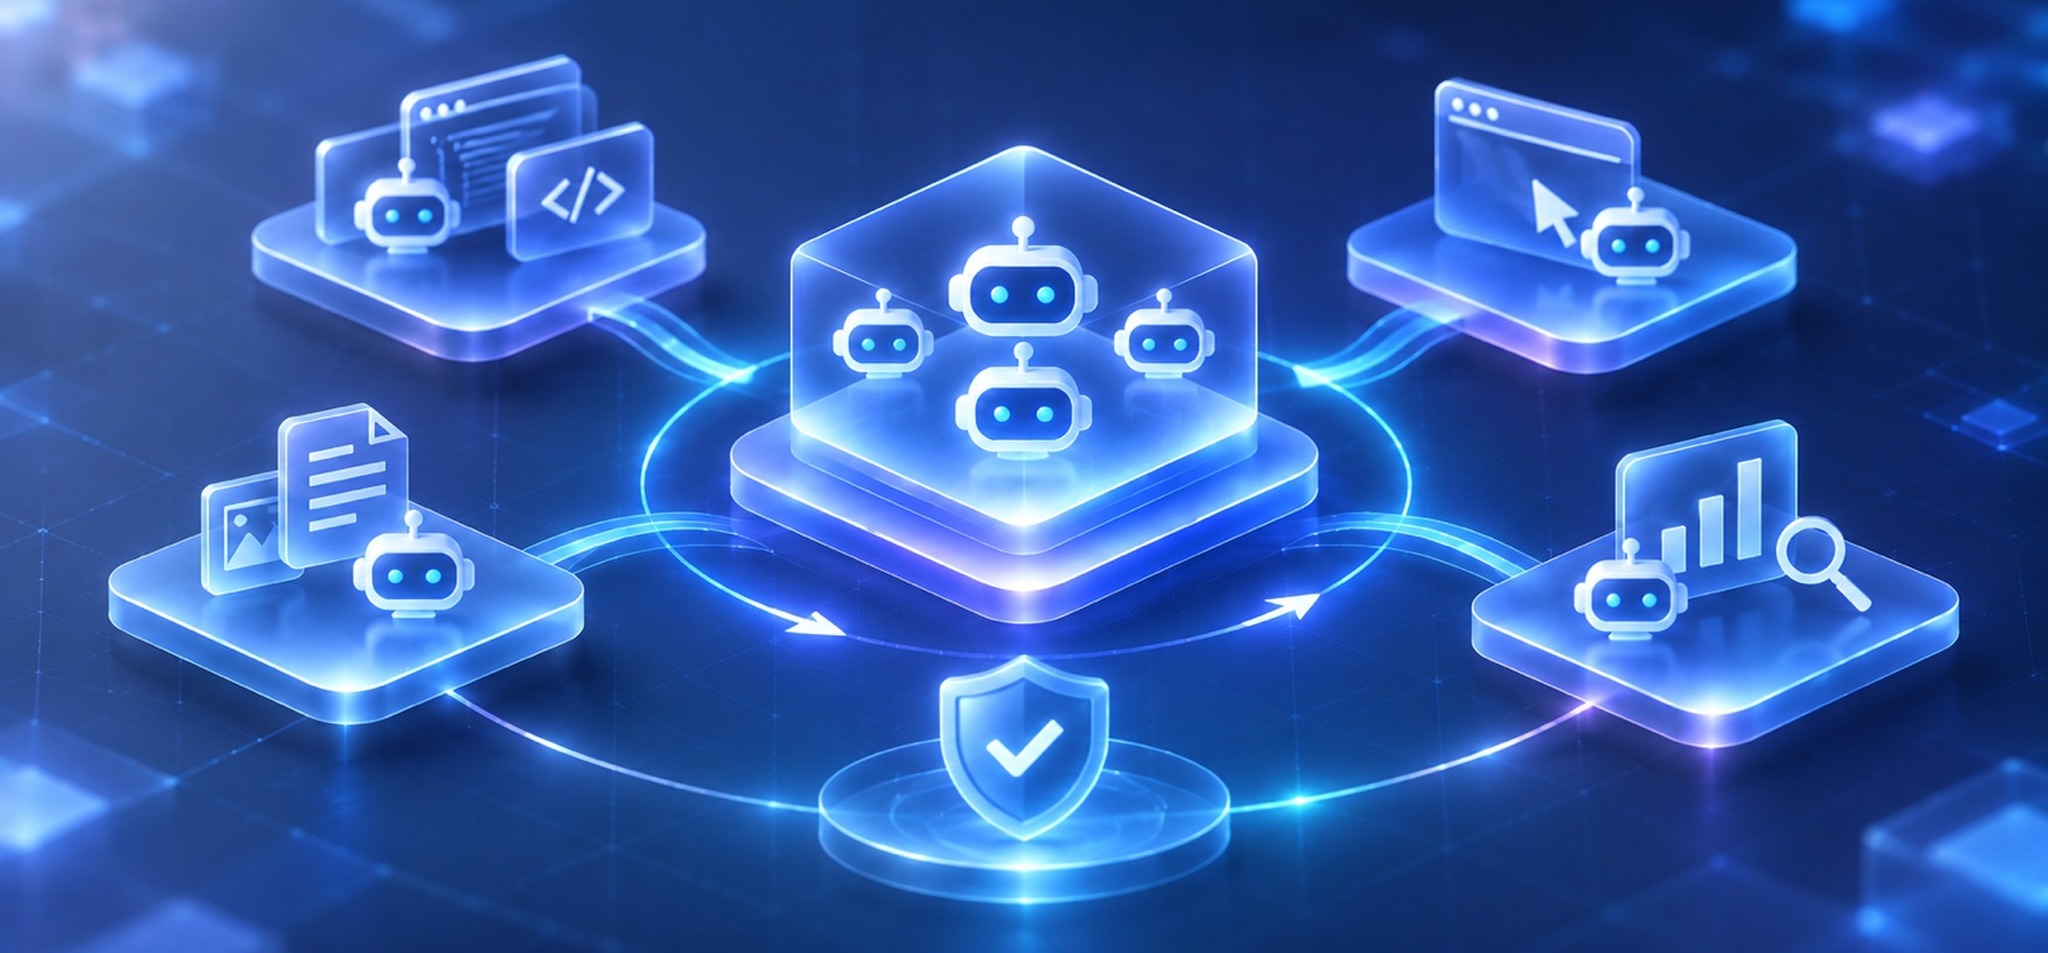
As artificial intelligence evolves from individual models into large-scale networks of autonomous agents, ensuring that these systems can coordinate efficiently, recover from failures, and operate with measurable reliability is becoming an increasingly important research challenge. Computer scientist Rui Yang is exploring these questions through research on multi-agent systems, AI reliability, and rigorous evaluation.
Artificial intelligence is undergoing a significant transformation. With advances in large language models and autonomous agent technologies, AI systems are moving beyond generating content and answering questions toward planning complex tasks, interacting with software, and collaborating with other agents. However, as autonomous systems expand from individual agents to groups of dozens, hundreds, or potentially more, their technical challenges become increasingly complex. How can multiple agents coordinate efficiently? How can a system avoid conflicting decisions? What happens when an agent fails to complete its task? And how can researchers determine whether a large-scale autonomous system is genuinely reliable?
These questions are central to the research interests of Rui Yang, a computer scientist who earned his Ph.D. in Computer Science from the University of California, Riverside. Yang’s research spans multi-agent path planning, autonomous AI systems, intelligent software debugging, and machine learning, with a particular focus on scalability, reliability, and systematic evaluation. His broader research objective is to develop technical methods that help increasingly autonomous AI systems operate efficiently, recover from failures, and demonstrate measurable performance under complex conditions.
Advancing Large-Scale Multi-Agent Coordination
Traditionally, many artificial intelligence systems have focused on the capabilities of individual models or agents, such as recognizing images, answering questions, or solving specific planning problems. With the development of autonomous AI agents, increasingly complex tasks can be divided among multiple specialized agents responsible for planning, execution, information retrieval, and verification. This approach creates opportunities to extend the capabilities of AI systems beyond what individual agents can accomplish.
However, large-scale collaboration also introduces new challenges. When many agents operate simultaneously, their decisions may interfere with one another. They must coordinate their actions, avoid conflicts, and maintain efficiency despite limited computational resources and changing environmental conditions. Yang’s earlier research investigated these challenges through multi-agent pathfinding (MAPF), a field concerned with planning coordinated movements for multiple agents in shared environments.
In Pruning and Prediction-based Priority Planning, published at the 2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), Yang and his collaborator introduced P4, an approach combining pruning and prediction techniques for priority-based multi-agent planning. The study investigated methods for improving computational efficiency while maintaining solution quality in multi-agent pathfinding. This research reflects an important aspect of Yang’s broader work: understanding how autonomous systems can maintain effective coordination as their scale and complexity increase.
Improving Reliability Through Distributed Coordination and Failure Recovery
Efficient planning is only one part of the challenge facing large-scale autonomous systems. In realistic environments, new tasks may appear, operating conditions may change, and previously generated plans may become infeasible. As a result, reliable autonomous systems must do more than produce an initial plan. They must also recognize unsuccessful decisions and adapt their behavior when circumstances change.
Yang further explored these challenges in Distributed Regional Efficient Agent Management with LLMs for Online MAPF, known as DREAM. The research investigates a distributed regional management approach to online multi-agent pathfinding and incorporates large language models into the coordination process. DREAM also explores failure reflection and replanning mechanisms, allowing unsuccessful planning attempts to be reconsidered and alternative solutions to be generated.
From P4 to DREAM, Yang’s research expanded from efficient multi-agent planning toward dynamic coordination and failure recovery. These studies address a broader technical objective: improving the ability of autonomous systems to maintain dependable coordination as their size and operational complexity increase. Such challenges have potential relevance to multi-robot coordination, intelligent warehouses, distributed automation, and other applications involving multiple autonomous decision-making entities.
Why AI Reliability Requires Rigorous Evaluation
As AI agents become increasingly capable of executing complex tasks, researchers face another important question: how should the reliability of autonomous AI systems be measured? Traditional machine learning evaluation often focuses on model accuracy or performance on fixed benchmark datasets. Autonomous agents, however, operate differently.
An AI agent may need to execute a long sequence of actions, interact with external tools, respond to unexpected changes, and revise its decisions based on intermediate results. Even when a system eventually completes a task, its execution process may involve unnecessary actions, temporary failures, or unstable behavior. Similarly, an unsuccessful task may result from environmental changes, tool limitations, or coordination failures rather than the reasoning capability of an individual model.
For these reasons, evaluating autonomous AI systems requires more comprehensive methodologies. Yang’s broader research interests include systematic approaches to understanding agent performance, identifying failure modes, and assessing reliability under realistic operating conditions. Relevant evaluation dimensions include task success rates, execution consistency, robustness, failure detection, recovery effectiveness, and performance across different environments.
For large-scale multi-agent systems, researchers must also investigate how reliability changes as the number of agents and the complexity of their interactions increase. Rigorous evaluation can help researchers compare competing methods, identify system limitations, and develop more effective approaches to improving autonomous AI performance. From this perspective, reliability and evaluation are closely connected.
Improving reliability requires understanding why systems fail, while meaningful evaluation requires methods that can capture failures, recovery behavior, and overall system performance. Together, these research directions may help establish stronger technical foundations for trustworthy autonomous AI.
Extending Autonomous AI Research to Software Engineering
Beyond multi-agent planning, Yang has explored agent-based approaches to software engineering and automated reasoning. In DOTA: Intelligent Debugging with Delta of Thoughts Agents, Yang and his collaborators investigated how agent-based reasoning methods could support software error diagnosis and repair. Software debugging presents a challenging problem for autonomous AI systems.
Identifying and correcting a defect may require understanding program behavior, reasoning about possible causes, generating alternative solutions, and verifying whether a proposed modification resolves the original problem. These tasks involve more than generating code. They require structured reasoning, evaluation, and the ability to identify unsuccessful solutions. Agent-based approaches offer opportunities to organize these processes and investigate how intelligent systems can address complex software engineering problems.
Yang has also participated in research on case-based language model reasoning through CaseGPT and multimodal machine learning through Enhancing Multi-Modal Relation Extraction with Reinforcement Learning Guided Graph Diffusion Framework, published at COLING 2025. Although these projects address different technical challenges, they reflect a continuing interest in developing and evaluating advanced AI methods across complex tasks. Taken together, Yang’s research connects multi-agent coordination, intelligent reasoning, failure analysis, and empirical evaluation as related aspects of autonomous AI development.
The Growing Importance of Reliable Large-Scale AI Agents
As artificial intelligence becomes more integrated into scientific research and enterprise workflows, future autonomous systems may involve multiple specialized agents collaborating on complex tasks. For example, an AI-assisted software development workflow could include separate agents responsible for requirements analysis, code generation, testing, debugging, and result verification. Such systems have the potential to support more complex forms of automation.
However, their practical usefulness will depend on whether the agents can coordinate reliably and whether errors can be detected before they affect the entire workflow. If a planning agent generates an incorrect sequence of actions, other agents may continue operating based on that mistake. If a verification agent fails to identify a defect, a local error may propagate through subsequent stages of the process.
These challenges become more difficult as the number of agents and the complexity of their interactions increase. Consequently, advancing large-scale AI agents requires more than developing increasingly powerful models. It also requires scalable coordination mechanisms, systematic failure analysis, effective recovery strategies, and rigorous quality evaluation.
Yang’s long-term research direction aims to connect these elements into a broader technical approach for developing dependable autonomous systems. The potential applications extend across intelligent software engineering, complex automation, robotics, and other fields that require coordinated autonomous decision-making.
Moving Beyond Capability Demonstrations
Artificial intelligence research is gradually expanding from demonstrating that systems can perform individual tasks toward understanding whether they can perform those tasks consistently under different conditions. For autonomous AI systems, a successful demonstration does not necessarily establish dependable performance. Researchers must also investigate when failures occur, how systems respond to unexpected conditions, and whether their capabilities generalize across tasks and environments.
This shift places increasing importance on reproducible evaluation, robustness analysis, and system-level reliability. For large-scale multi-agent systems, the challenge becomes even greater because performance depends not only on the capabilities of individual agents but also on how they interact. Yang’s future research interests include connecting scalable multi-agent coordination with systematic reliability evaluation and failure recovery methodologies.
By investigating these challenges, he aims to contribute technical methods that help researchers and engineers better understand the limitations of autonomous AI systems and identify opportunities for improvement. The broader objective is to support the development of AI technologies whose performance can be measured, analyzed, and improved through rigorous evaluation.
Toward Trustworthy Large-Scale Autonomous AI
Artificial intelligence is moving toward increasingly autonomous and collaborative systems capable of performing complex tasks. This transformation creates significant opportunities for scientific and industrial applications, but it also makes reliability and evaluation essential research challenges. From efficient multi-agent planning in P4 to distributed coordination and failure recovery in DREAM, and intelligent software debugging in DOTA, Yang’s research reflects a continuing effort to investigate the capabilities and limitations of complex autonomous systems.
These studies contribute to a broader research vision: advancing large-scale AI agents that can coordinate efficiently, respond to failures, and demonstrate measurable reliability through rigorous evaluation. As autonomous AI systems take on increasingly complex responsibilities, their practical value may depend not only on how capable individual agents become but also on whether entire systems can operate reliably at scale. For Yang, advancing large-scale AI agent technologies and developing reliable evaluation methodologies are not separate objectives.
They are complementary parts of a long-term research direction aimed at building more scalable, dependable, and trustworthy autonomous artificial intelligence systems.




Comment