
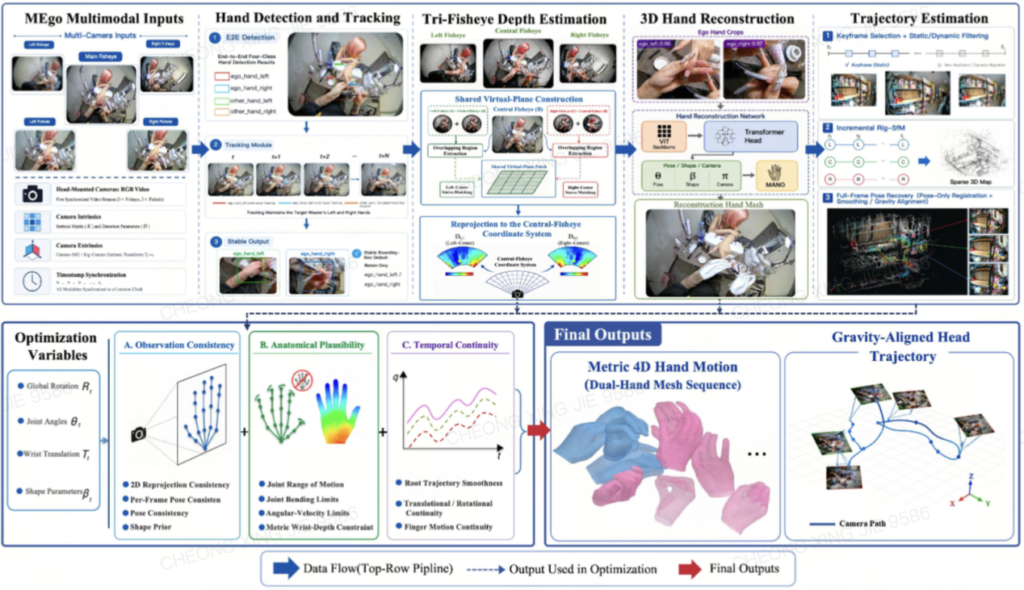
Maniformer, together with researchers from Northwestern Polytechnical University and Xi’an Jiaotong University, present MEgoVista, an offline system that turns egocentric video recorded with the MEgo View headset into metric-scale 4D motion of both hands and the head.
Paper: https://arxiv.org/abs/2609.16684
Egocentric (Ego) video is bringing data collection out of specialized facilities and into real-world living and working environments, and is becoming an important source of data for embodied AI pretraining. But recording an activity does not automatically yield the motion data required for pretraining embodied models. A system must still accurately identify which hands belong to the wearer, how the fingers bend, and how far the hands move in space: a distance in real-world units, not a scale-free estimate.
Why Is Measuring Egocentric Motion Accurately So Hard?
For Ego video to be useful during model training, human actions must be accurately “translated” into robot actions. Many challenges remain along the pipeline from video collection to motion reconstruction.
Existing approaches force a trade-off. Multi-camera studio systems are accurate but require preinstalled equipment and cannot leave the lab. Large everyday-life video datasets cover diverse scenes but lack metric-scale 3D hand annotations, so they cannot provide actual hand positions or movement distances.
Single-camera methods face a further limit: distance is inferred from patterns learned in training rather than measured, so a reconstruction can match the hand in the image yet sit in the wrong place in 3D. Real activities add more problems. In a manicure, the wearer’s and a bystander’s hands appear together and must not be confused; fingers are blocked by tools or forearms; and head turns move the camera, so hand motion must be separated from camera motion.
Three Steps to Reconstruction: Identify the Hands, Measure Distance, Refine Motion
MEgoVista uses an offline reconstruction pipeline built on three steps:
- Identify the wearer’s hands. MEgoVista detects hands, tells left from right, and determines which belong to the wearer, so a bystander’s hands are not mistaken for the wearer’s, even when they touch.
- Measure distance with multiple cameras. The MEgo View headset has three fisheye cameras recording at 60 frames per second. The center camera is paired with each side camera to form two stereo pairs. Using pre-calibrated camera baselines, the system rectifies the images, estimates depth with FoundationStereo, and fuses the two results, favoring higher-confidence estimates.
- Refine the full sequence. Rather than trusting each frame in isolation, MEgoVista filters for reliable observations and optimizes the whole sequence, producing smoother motion and finger poses that respect human anatomy.
For the head, the system reconstructs the trajectory from multi-camera imagery, fixes metric scale at initialization, and uses inertial data to determine the vertical direction. Hands and head are output in one shared metric-scale 4D coordinate system.
Evaluation Results: Higher Accuracy and More Reliable Hand Identification
The research team evaluated MEgoVista using reference data from a separate optical motion-capture system comprising 26 cameras. The evaluation also counted missed hand detections, so that a method could not improve its score by skipping difficult frames.
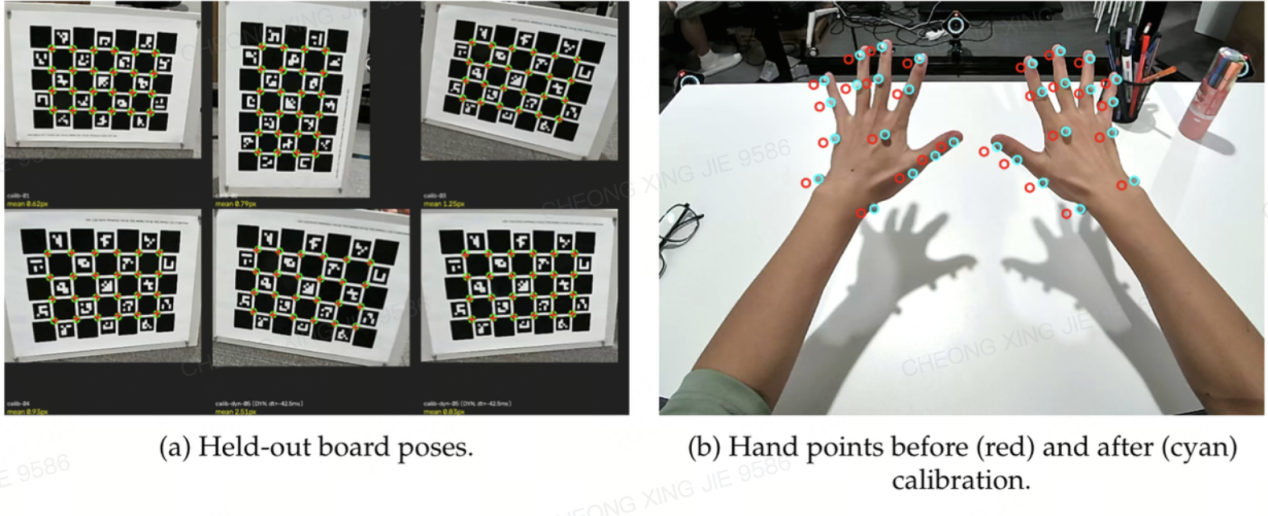
Verifying Alignment Between Motion-Capture Data and Camera Footage
In testing, MEgoVista’s finger pose error (PA-MPJPE-p) was 4.29 mm, compared with 16.30 mm for HaWoR and 49.18 mm for Dyn-HaMR. For absolute wrist position in the camera frame (CT-p), MEgoVista’s error was 14.30 mm, compared with 46.70 mm for HaWoR and 184.38 mm for Dyn-HaMR.
In this test set, MEgoVista produced no missed or false hand detections, while also achieving lower motion jitter than both baseline methods, at 1.11 mm/frame². In two head-trajectory tests, the average position errors over the complete sequences were 2.87 mm and 0.75 mm, respectively, compared with 3.27 mm and 1.00 mm for an offline-refined ORB-SLAM3 baseline.
The team also conducted further comparisons in three real-world scenarios:
- Milk-tea preparation: When both hands moved rapidly, the reconstructed skeletons of MEgoVista and Dyn-HaMR aligned closely with the hands, while HaWoR showed a pronounced misalignment in the left-hand skeleton.
- Manicure: Both HaWoR and Dyn-HaMR at times misattributed a bystander’s hand to the wearer when the two people’s hands came into contact. MEgoVista correctly distinguished between the two individuals.
- Animal washing: When hands were soiled and moving quickly, both MEgoVista and Dyn-HaMR detected the hands, whereas HaWoR showed displacement in the left hand and wrist.
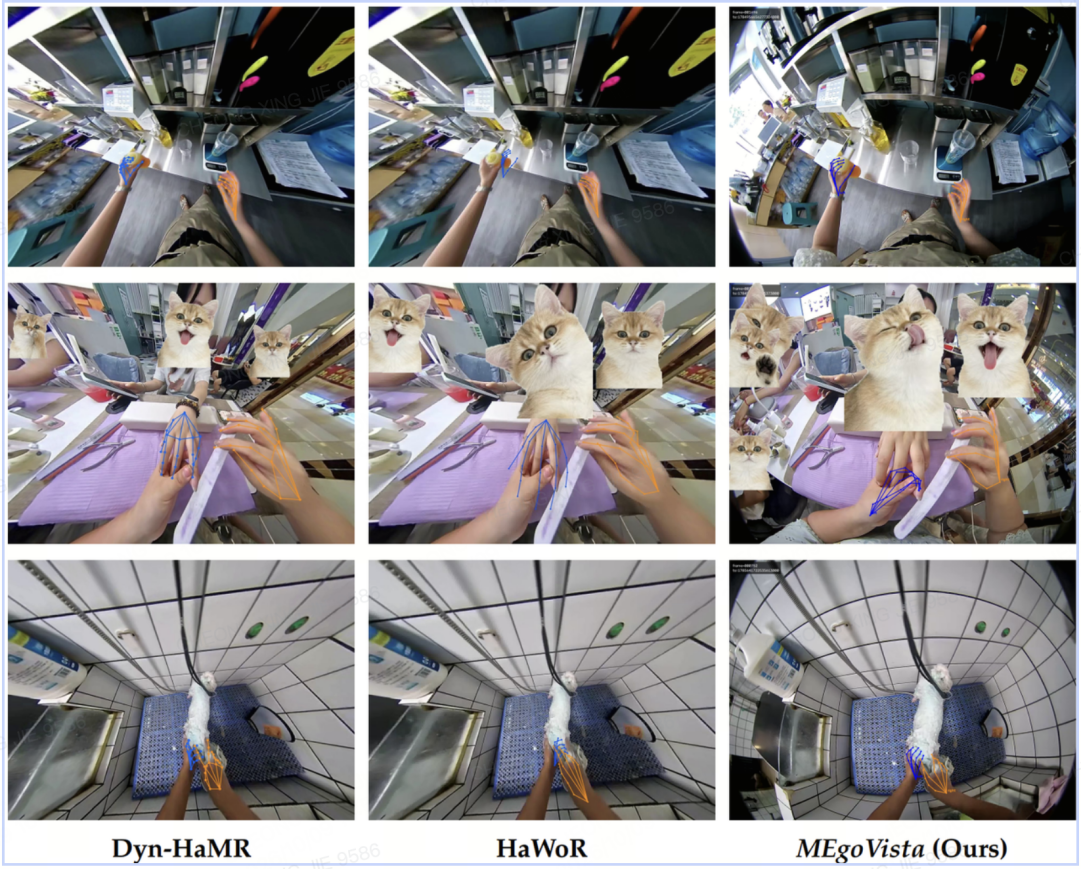
The visual comparisons indicate that, in fast-paced activities and multi-person interactions, MEgoVista can detect hands more consistently, reconstruct skeletal motion that more closely aligns with the actual hand positions, and more reliably distinguish the wearer’s hands from those of other people.
MEgoVista reconstructs human manipulation in Ego video as metric-scale 4D motion and validates its reconstruction accuracy against independent reference measurements, providing a more reliable source of data for robot learning.
About Maniformer
Maniformer is a leading Physical AI data platform building the data infrastructure for embodied intelligence. Combining intelligent data-collection hardware, a powerful data engine, and end-to-end data services, Maniformer transforms real-world physical interactions into high-quality, scalable data. From collection and processing to validation and intelligent operations, Maniformer provides the data foundation that accelerates the development and deployment of Physical AI.
Find out more about Maniformer here: https://maniformer.ai/en