
The artificial intelligence landscape witnessed a significant shift in September 2026 with the back-to-back releases of Anthropic’s Claude Fable 5.1 and OpenAI’s GPT-6 Astra. Now fully integrated into the CometAPI platform, you can get Cometapi GPT-6 Astra here, and it is positioned not merely as a conversational upgrade, but as a specialized engine for complex, end-to-end execution.
By evaluating GPT-6 Astra against its highly capable predecessor, GPT-5.6 Sol, and its direct frontier competitor, Claude Fable 5.1, a clear picture emerges: the modern AI procurement decision has moved past simple intelligence leaderboards. Today, developers must optimize for the lowest cost per successfully completed agentic task.
How Much Does GPT-6 Astra Cost Through CometAPI?
CometAPI currently offers GPT-6 Astra API access with short- and long-context token rates 20% below the corresponding official rates.
- Short context: CometAPI lists $8/M input and $40/M output, compared with OpenAI’s $10/M and $50/M.
- Long context: CometAPI lists $16/M input and $60/M output, compared with OpenAI’s $20/M and $75/M.
- Cache: short-context read/write rates are $0.80/M and $10/M; long-context rates are $1.60/M and $20/M.
- Difference: the listed CometAPI rates are 20% below the matching OpenAI rates in each category. Confirm current rates before production budgeting.
GPT-6 Astra Core Specifications and Architectural Shifts
OpenAI’s GPT-6 Astra features a 1.05-million-token context window and a maximum output capacity of 128,000 tokens. Processing both text and image inputs to generate text, the model operates with a knowledge cutoff of April 30, 2026.
What distinctly separates GPT-6 Astra from previous generations is its workflow architecture, which is custom-built for long-running autonomous agents:
- Asynchronous Tool Calling: GPT-6 Astra can continue independent reasoning or trigger other functions while waiting for a slow, external tool to finish.
- Mid-Turn Steering: Through a Responses WebSocket connection, applications can inject new instructions or correct constraints mid-task without discarding the work GPT-6 Astra has already completed.
- Dynamic Reasoning Updates: Developers can toggle reasoning effort between responses (from low to max) without rebuilding the cached prompt prefix. Notably, GPT-6 Astra removes the none reasoning option that is available in GPT-5.6 Sol, reflecting its focus on intensive cognitive tasks.
GPT-6 Astra Benchmark Performance: Execution Over Generation
The benchmark narrative surrounding GPT-6 Astra is one of operational execution rather than simple question-answering superiority.
Gpt-6 Astra vs. GPT-5.6 Sol
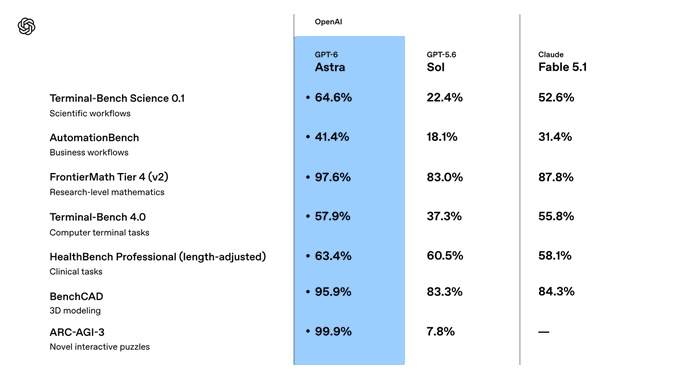
When compared to GPT-5.6 Sol, GPT-6 Astra shows modest gains on standard academic tests. For instance, a mere 1.4-point increase on GPQA Diamond (96.0% vs. 94.6%). However, the gap becomes a chasm when the models are asked to operate environments. On Terminal-Bench 4.0, GPT-6 Astra scores 57.9% against Sol’s 37.3%. On AutomationBench, it leaps to 41.4% from Sol’s 18.1%.
Furthermore, GPT-6 Astra is substantially faster at completing these complex loops. In OSWorld 2.0 latency simulations, GPT-6 Astra averaged 40 minutes per task compared to Sol’s 75 minutes, a 47% reduction in elapsed time that directly impacts throughput for enterprise automation.
GPT-6 Astra vs. Claude Fable 5.1
The comparison against Anthropic’s Claude Fable 5.1 reveals a fascinating split in frontier capabilities.
- The Case for GPT-6 Astra : GPT-6 Astra maintains a distinct edge in execution-heavy coding and scientific tooling. It leads Fable 5.1 on Terminal-Bench 4.0 (57.9% vs. 55.8%), DeepSWE v1.1 (74.1% vs. 67.4%), and internal database migration tasks (63.9% vs. 57.8%). It also dominates specialized technical benchmarks like FrontierMath Tier 4 v2 (97.6% vs. 87.8%).
- The Case for Fable 5.1: Claude Fable 5.1 excels in broad, multidisciplinary reasoning. It defeats GPT-6 Astra on Humanity’s Last Exam with tools (65.0% vs. 57.2%) and scores higher on the Artificial Analysis Intelligence Index (65.7 vs. 61.2). Fable’s architecture, featuring turn-scoped system messages and always-on adaptive thinking, makes it a formidable engine for sustained, long-horizon deliberation.
The Impact of the Evaluation Harness
Frontier benchmarks increasingly measure the entire system architecture rather than an isolated model. On the ARC-AGI-3 benchmark, GPT-6 Astra scores 62.7% using the Standard harness at maximum effort. However, when utilizing a Provider Adapter that retains additional reasoning state and uses provider-specific context management, the score increases to 99.9%. This indicates that the surrounding application infrastructure heavily influences the final output quality.
Long-Context Architecture and Preservation
Both GPT-6 Astra and Fable 5.1 advertise context windows of approximately 1 million tokens, but capacity does not equal usability. Traditional long-context systems rely on compaction and summarization, which frequently discard critical operational details, such as why a previous code fix failed or the specific output of a background tool.
GPT-6 Astra addresses this by utilizing internal context preservation and retrieval mechanisms inside long-running workflows. In the MRCR v2 synthetic retrieval evaluation at the 512K–1M token range, GPT-6 Astra scores 96.3% compared to GPT-5.6 Sol’s 73.8%. This 22.5-point margin demonstrates a superior ability to recover specific evidence near the limits of the context window.
The Economics of Agentic Workloads
The most complex dimension of adopting GPT-6 Astra is its cost structure. At base OpenAI rates, GPT-6 Astra ($10 per million input tokens / $50 per million output tokens) is 2.5 times more expensive than GPT-5.6 Sol.
- The Long-Context Surcharge: Astra’s input and cache rates double for requests exceeding 272,000 input tokens. Fable 5.1 maintains its standard rate across its entire 1M-token window.
- Cache-Read Pricing: Anthropic priced Fable 5.1’s cache reads at $0.25 per million tokens. GPT-6 Astra charges $1.00 for standard cache reads and $2.00 in the long-context tier. For agentic loops that repeatedly read large static repositories, Anthropic estimates Fable 5.1 can reduce workload costs by 25% to 45%.
Security and Boundary Adherence
As models gain the ability to autonomously operate systems, safety boundaries become critical. GPT-6 Astra is the first OpenAI model to reach the “Critical” cybersecurity capability threshold, having scored 39.0% on ExploitBench (June-August 2026) compared to Sol’s 5.5%, and successfully discovering zero-day vulnerabilities in controlled testing. Consequently, it requires strict deployment monitoring.
However, GPT-6 Astra is highly disciplined. In tests observing boundary adherence, GPT-5.6 Sol failed 48% of the time without production safeguards, whileGPT-6 Astra stayed within authorized bounds 100% of the time. Similarly, its susceptibility to indirect prompt injections (8.5%) is lower than Sol’s (27.0%).
Final Verdict: Evaluating Cost Per Successful Task
The availability of GPT-6 Astra, GPT-5.6 Sol, and Claude Fable 5.1 through the CometAPI gateway allows organizations to test workloads across models without altering their primary architecture.
The determining factor for procurement is the total expected business cost per successful task; calculating API charges, tool costs, retry expenses, and human review time against the number of verified successes.
- GPT-5.6 Sol: Remains the most economical option for straightforward, high-volume classification, summarization, and bounded code generation where the model reliably passes acceptance criteria.
- Claude Fable 5.1: The optimal choice for long-horizon asynchronous agents, broad multidisciplinary reasoning tasks, and workflows relying on heavy prompt-cache reuse due to its highly efficient cache-read rate.
- GPT-6 Astra: The primary choice when execution is the operational bottleneck. If the task requires sustained tool interaction, complex database migrations, or precise retrieval across massive document archives, Astra’s higher success rates and lower human-correction burden frequently offset its higher per-token price.